Vllm
2026
How Caktus Runs and Uses Local Models
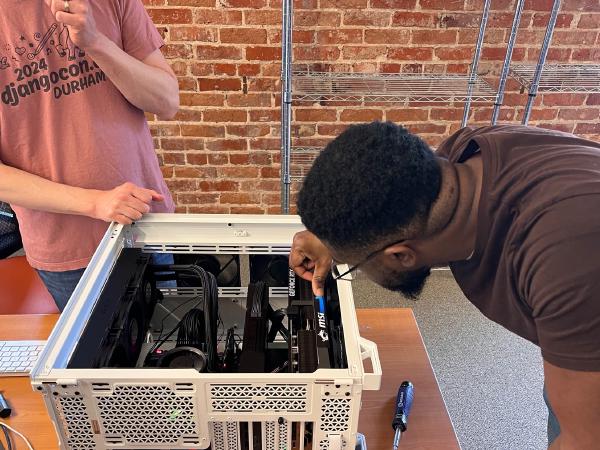
As a research project this year at Caktus, we’ve been experimenting with serving open-weight language models on our own hardware. In this post, we’ll walk through the hardware, the Docker Compose stack that serves our models, the Gemma and Qwen configurations we tested, our benchmarks, and the configurations we use in pi.dev and VS Code.